Is it possible to effectively automate equity investment reporting?
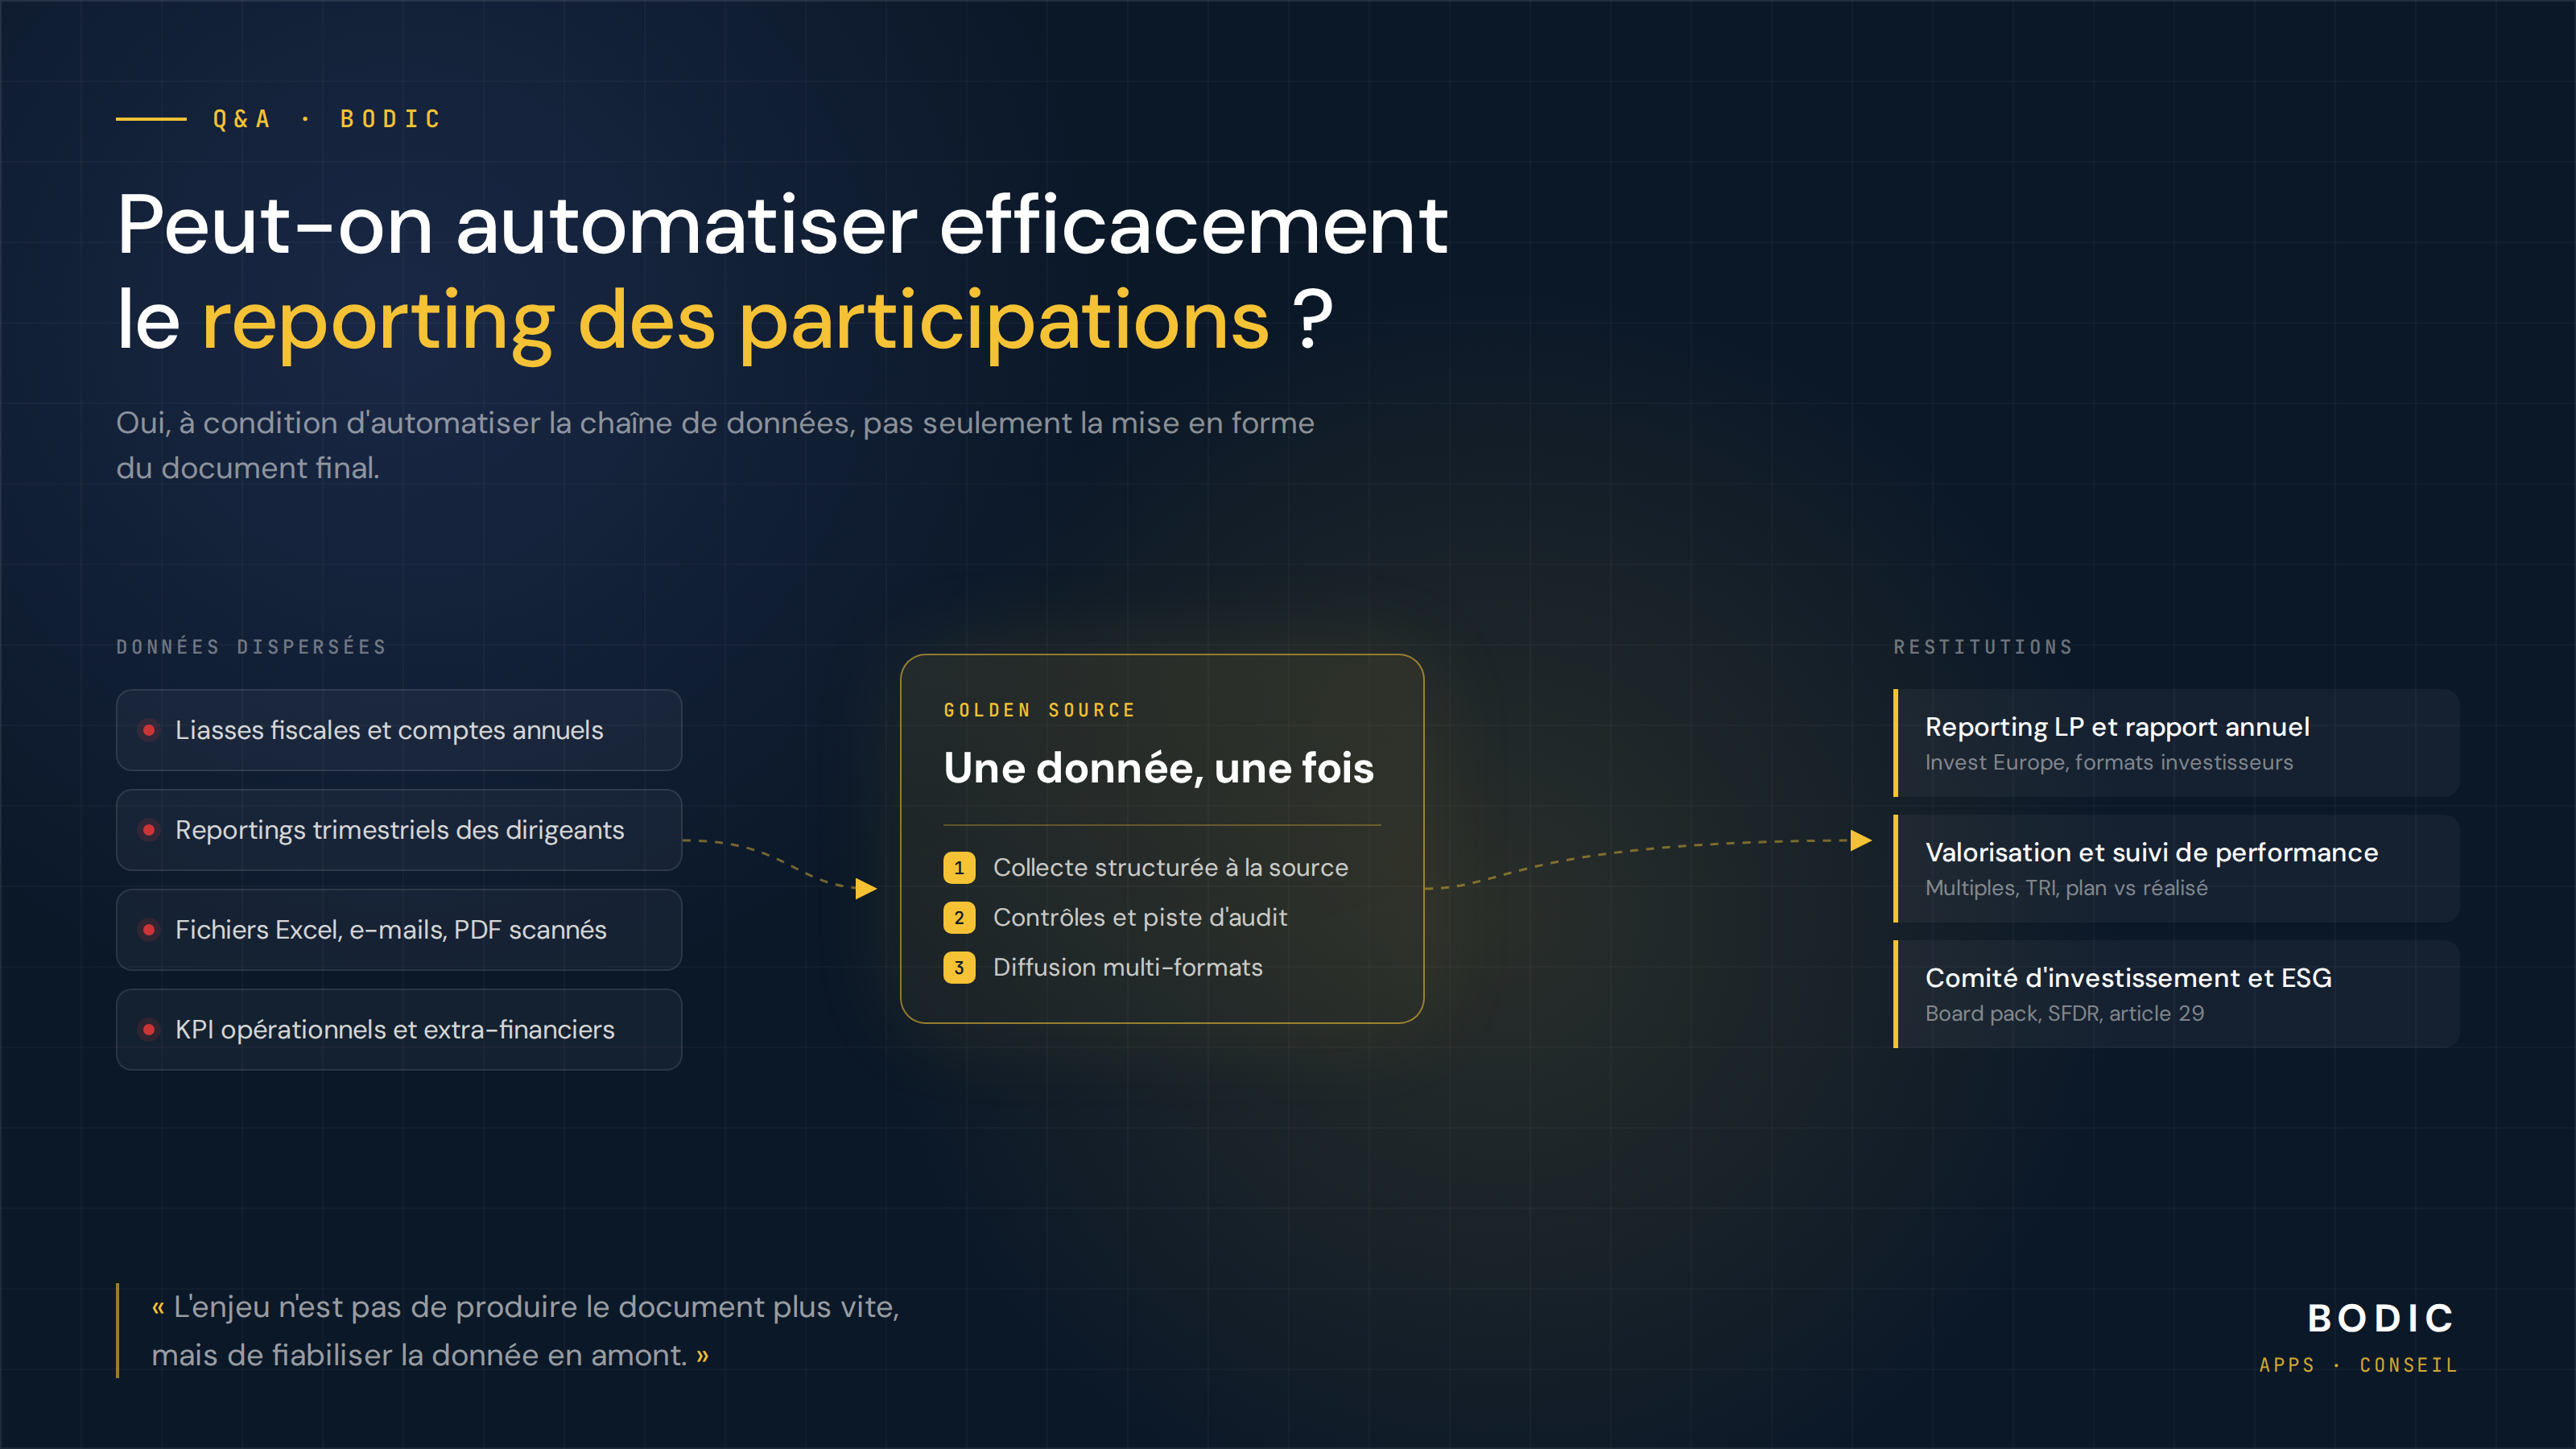
Yes, provided that the data pipeline is automated—not just the formatting of the final document. Most projects fail because they focus on the “last mile”—the LP report or board pack—when the real cost lies upstream: collecting, re-entering, and validating information produced by third parties in different formats and on different schedules.
Three levels of automation, in order of increasing value. First, data collection: a structured data entry portal open to executives at portfolio companies replaces the back-and-forth email cycle and makes the closing date predictable. This is the most significant—and most underestimated—source of savings. Next comes verification: consistency with the previous quarter, variances from the budget, and completeness, with an audit trail that answers the question, “Where does this figure come from?” Finally, reporting—which becomes a simple matter once the data is consolidated, dated, and validated.
There remains one line that must not be crossed. The selection of comparables, the treatment of an exceptional event, and the commentary provided to limited partners are matters of the manager’s judgment. The goal is not to remove the human element, but to reallocate it: less time spent fabricating the numbers, more time spent explaining them.
This is the approach adopted by Bodic Apps, where Portfolio Portal, Middle Office, and Golden Source share the same data rather than duplicating it. The preliminary framework, the set of performance metrics, and change management for portfolio companies are the responsibility of Bodic Conseil.
The question of where to start with AI in a fund is often approached from the wrong angle. The point is not to choose a tool, but to identify where AI can concretely improve operational efficiency, data quality or decision quality.
In the majority of asset management companies, the first gains are not to be found in complex or "spectacular" applications. Instead, they appear on repetitive, time-consuming tasks with little intellectual added value: consolidating reports, preparing summaries, searching for information in documents, producing reports, structuring data from heterogeneous files or processing recurring e-mails.
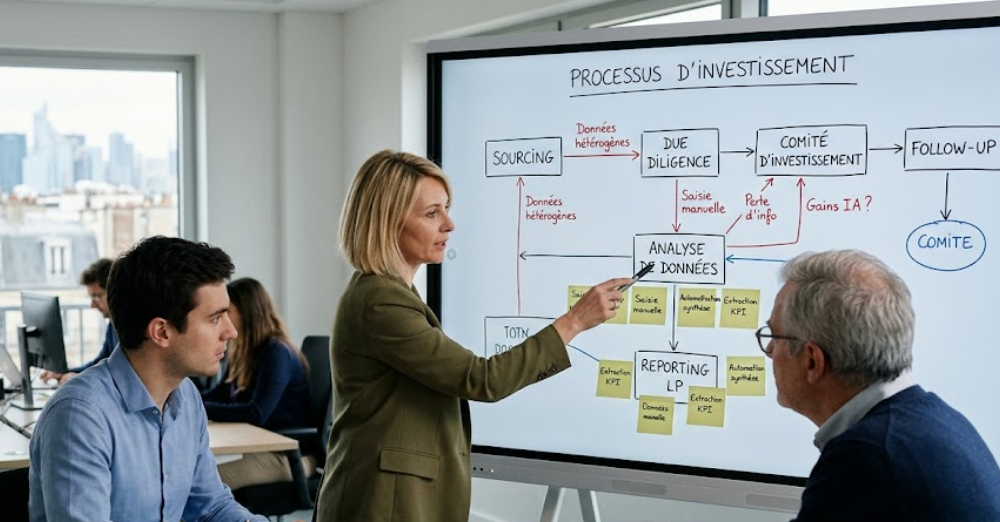
The first step is to analyze existing processes. We need to understand how teams actually work: where data flows, what tools are used, where there is double entry, manual reprocessing, loss of information or Excel dependencies.
This mapping phase is essential, as it identifies areas of operational friction and points where AI can bring immediate gain without profoundly changing organizations.
The second step is to structure the data chain to a minimum. Even high-performance AI produces weak results if it relies on inconsistent, dispersed or ungoverned data. You don't need to build a complex architecture right away, but you do need a reliable foundation: centralized data, common definitions and minimal validation rules.
Once this foundation has been laid, it's possible to launch a few targeted use cases, with three characteristics: limited scope, measurable value and low operational risk.
The most effective projects are often highly pragmatic: automating memo summaries, extracting information from a data room, preparing LP reports, assisting document research or structuring participative KPIs.
The classic mistake is to try to deploy a global AI strategy before having stabilized the data and operational fundamentals. Conversely, funds that move forward effectively are those that build progressively: structuring data, first business use cases, ramping up team skills, then industrialization.
AI should be thought of as a layer of acceleration on top of an already mastered organization. Without solid foundations, it amplifies existing weaknesses. With a structured data chain and well-defined uses, it becomes an extremely powerful operational lever.
What new roles are emerging in a fund with AI and Data?
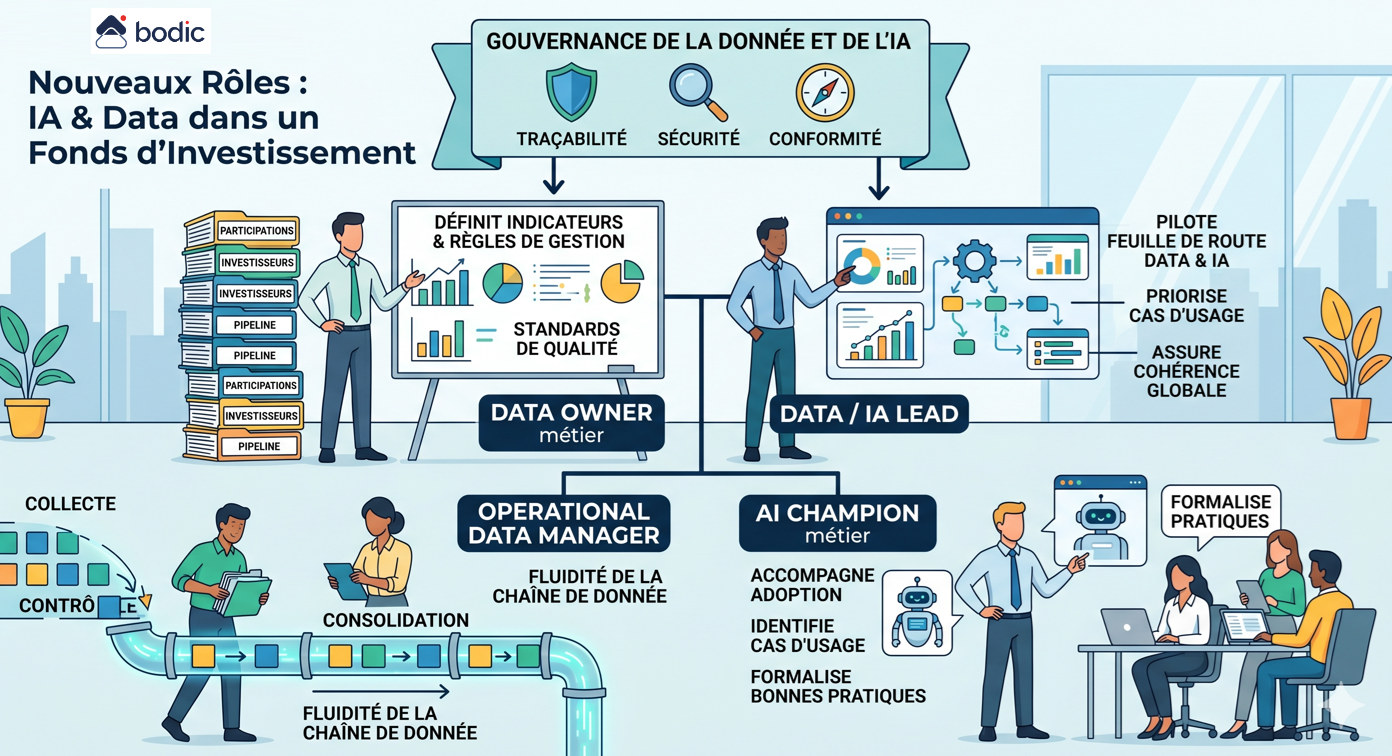
The introduction of AI and Data into a fund doesn't create an abrupt disruption of business lines, but does give rise to new roles around data structuring, governance and operational use.
The first key role is that of business Data Owner. He or she is responsible for a critical perimeter of data, such as shareholdings, investors or the pipeline. He or she defines indicators, management rules, expected formats and quality standards. Without this role, data remains diffuse and difficult to exploit.
The second role is that of Data / AI Lead. He/she steers the fund's Data and AI roadmap, prioritizes use cases, arbitrates tool choices and ensures overall consistency. He acts as a point of convergence between the investment teams, Middle Office, IR and support functions.
A third role is emerging around the Operational Data Manager. Located at the heart of operations, often in the Middle Office, he or she ensures that data flows are correctly collected, controlled, consolidated and disseminated. He or she is responsible for the operational quality and fluidity of the data chain.
With AI, a more specific role of Business AI Champion is also emerging. This profile is not necessarily technical, but has a thorough command of the tools and their uses. He or she supports teams in their adoption, identifies relevant use cases and formalizes best practices, particularly with regard to the supervision and limits of AI agents.
Finally, a cross-functional role for Data and AI Governance is becoming essential. This covers traceability, security, compliance and control. In an LP and regulatory context, the ability to explain a piece of data or a decision becomes as important as producing it.
It's not necessary to set up a dedicated team right away. In most funds, these roles emerge gradually from existing teams. The challenge is to identify responsibilities, clarify scopes of work and structure targeted skills development.
The key point is to ensure that they are rooted in the business. These roles must not be isolated in a purely technical logic, but integrated into the heart of the investment and management processes. It is this proximity that enables data to be transformed into a real performance lever.
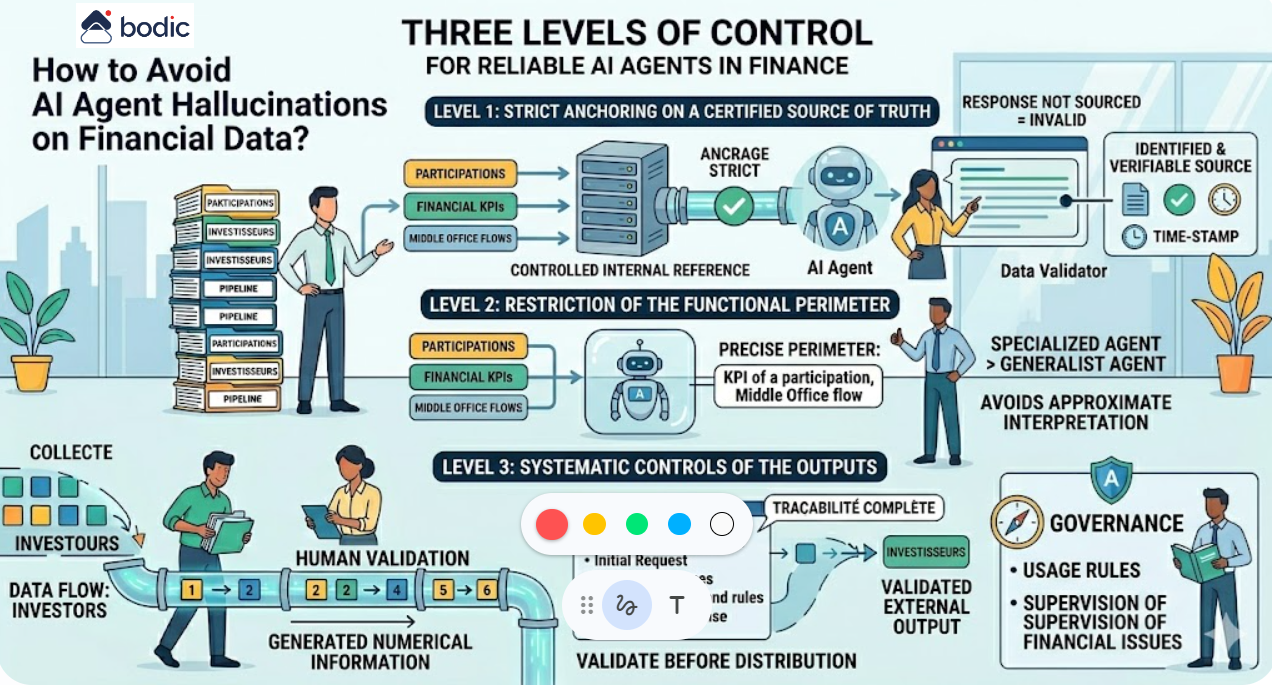
How to prevent an AI agent from hallucinating financial data?
Hallucinations are the main risk when using AI agents in a financial context. They are not the result of random errors, but of the structural behavior of models in the absence of reliable or sufficiently constrained information.
Three levels of control can greatly reduce this risk.
The first is strict anchoring on a certified source of truth. The agent must not rely on general knowledge or implicit data, but only on a controlled internal repository. Each answer must be associated with an identifiable, accessible and verifiable source. An unsourced answer must be considered invalid by default.
The second level is the restriction of the functional and informational perimeter. An agent must intervene in a precise domain, with a limited and controlled set of data. The wider the scope, the greater the risk of approximate interpretation. In practice, an agent who specializes in a subset of financial data, such as a shareholding's KPIs or Middle Office flows, is significantly more reliable than a generalist agent.
The third level is the implementation of systematic controls on outputs. All numerical information intended for external use, in particular for investors, must be validated by a human being. This validation must be based on complete traceability: initial request, sources used, transformations applied and response generated.
Beyond these principles, technical architecture plays a decisive role. A structured approach consists in isolating the AI layer from raw data, using a centralized repository, then exposing only validated data to agents. This allows precise control over what the agent can see and use.
Finally, it's important to treat hallucinations as a governance issue, not just a technical problem. This means defining rules of use, levels of responsibility and supervisory mechanisms adapted to the financial stakes involved.
A reliable agent is not one that "responds well", but one whose every response can be explained, traced and verified.